


Building Reliable Data Engineering Pipelines for Modern Teams
Introduction
Every organization that collects information today, whether it's a five-person startup or a global enterprise, eventually runs into the same problem: raw data is messy, scattered, and useless until someone shapes it into something usable. That shaping work is the job of data engineering pipelines. They quietly move information from one system to another, clean it along the way, and hand it off to analysts, data scientists, and business leaders who depend on it to make decisions. Most people never see this machinery running in the background, yet almost every dashboard, report, or machine learning model they trust was built on top of it.
This article walks through what makes data engineering pipelines dependable, why so many teams struggle to keep them healthy, and what practical steps actually move the needle. The goal is grounded, experience-based guidance that reflects how these systems behave in the real world, not just in diagrams.
Why Data Engineering Pipelines Matter More Than Ever
Data volume has exploded across nearly every industry. Retailers track clickstreams, logistics companies monitor sensor feeds, and healthcare providers manage patient records that update by the second. Without a structured way to collect, transform, and deliver this information, teams end up drowning in spreadsheets and manual exports. Well-designed data engineering pipelines solve this by automating the tedious parts of data movement so people can focus on interpretation rather than plumbing.
There's also a trust dimension here. When a pipeline silently fails or delivers incomplete data, the damage isn't just technical. Executives lose confidence in reports, marketing teams make decisions on stale numbers, and finance departments risk compliance issues. A pipeline isn't just infrastructure; it's the foundation that determines whether an organization's data can actually be trusted.
The Core Building Blocks
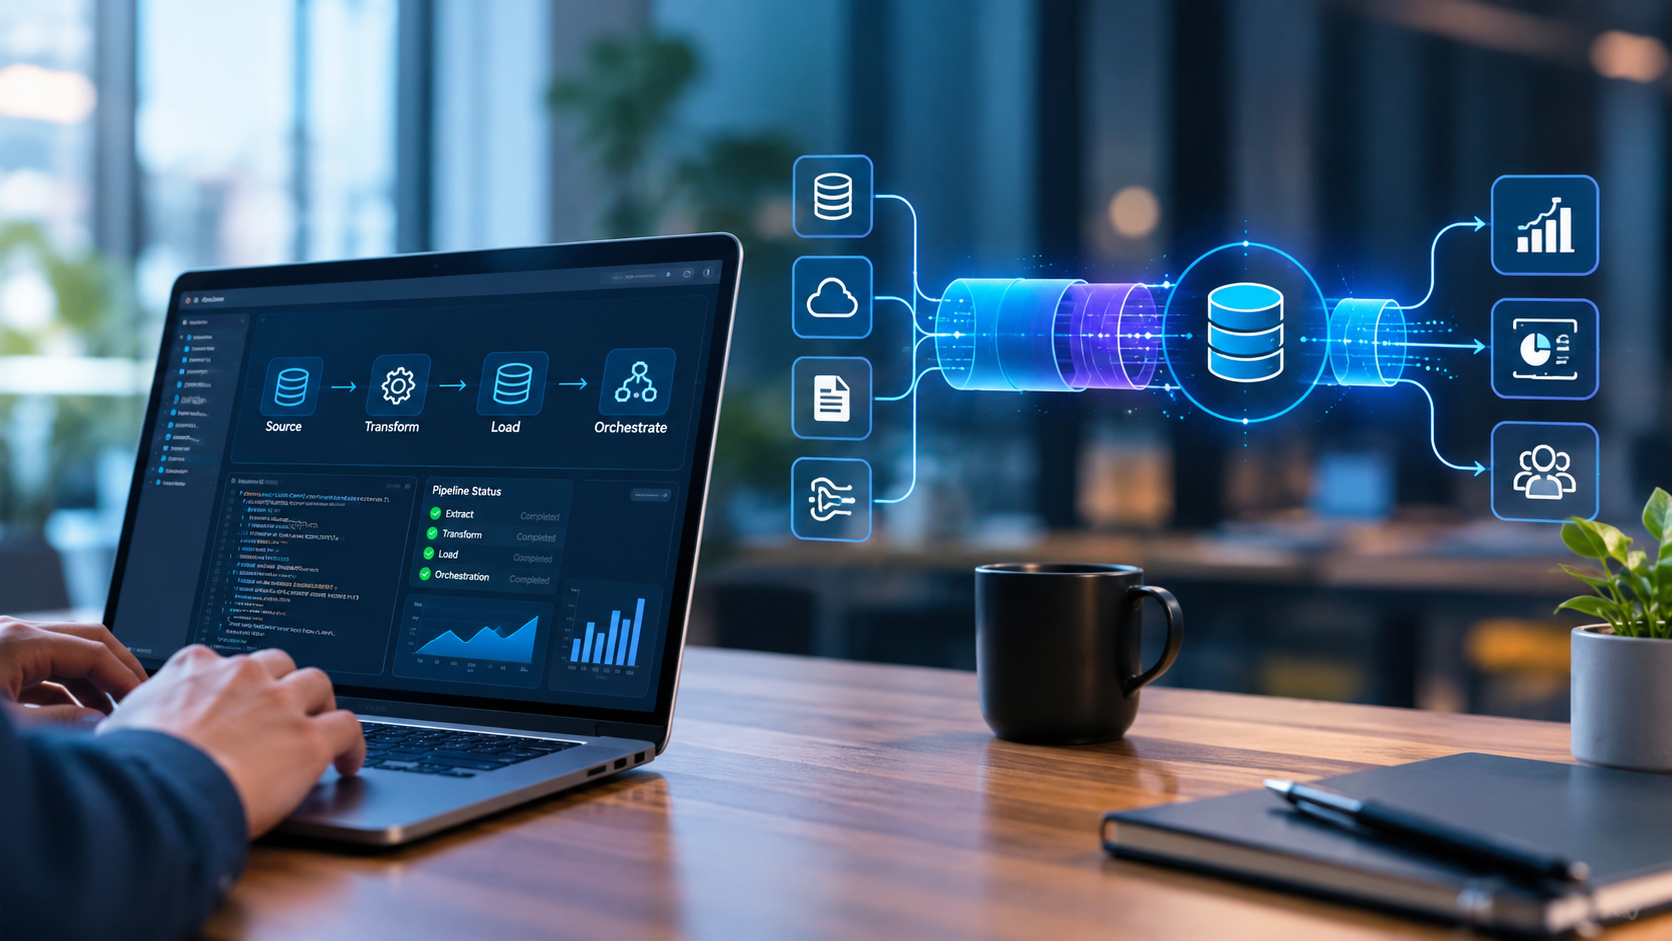
At their heart, most data engineering pipelines follow a familiar rhythm: extract data from a source, transform it into a usable shape, and load it into a destination where it can be queried or analyzed. This pattern, often shortened to ETL or its cousin ELT, has been around for decades, but the tools used to execute it have changed dramatically. Cloud-native warehouses, distributed processing engines, and orchestration platforms now handle workloads that would have overwhelmed on-premise servers a decade ago.
What separates a fragile setup from a resilient one usually comes down to how the pipeline handles failure. Source systems change their schemas without warning, APIs go down, and network calls time out. Teams that build their data engineering pipelines with retries, checkpoints, and clear alerting recover quickly from these hiccups. Teams that don't tend to discover problems only after a stakeholder notices something wrong in a report, days too late.
Designing for Trustworthy Outcomes
Good pipeline design starts long before any code gets written. It begins with understanding who consumes the data and what decisions depend on it. Well-planned data engineering pipelines feeding a real-time fraud detection system have completely different latency and accuracy requirements than one feeding a monthly executive summary. Skipping this discovery step is one of the most common reasons projects run over budget or deliver something nobody actually needed.
Data quality checks deserve special attention here. It's tempting to assume that once data lands in a warehouse, the job is finished. In practice, validation should happen at every stage: when data enters the system, after each transformation, and again before it reaches end users. Catching a broken field early is far cheaper than untangling a corrupted report that has already influenced a business decision. Many experienced engineers treat validation not as a final gate but as an ongoing habit woven throughout the entire pipeline.
Documentation is another area that gets neglected until it's too late. When the person who built a pipeline leaves the company or moves to another project, undocumented logic becomes a liability. Clear naming conventions, inline comments explaining business logic, and a simple architecture diagram can save weeks of confusion later.
Common Mistakes That Undermine Data Engineering Pipelines
One recurring issue is over-engineering. Teams sometimes reach for the most sophisticated distributed system available when a straightforward scheduled script would have done the job just as well. Complexity should scale with actual need, not with what looks impressive on a resume. Another frequent mistake is ignoring cost. Cloud compute and storage bills can balloon quickly when transformations run more often than necessary or when intermediate data is never cleaned up.
Security is often an afterthought too. Sensitive fields like customer emails or payment details sometimes flow through pipelines without masking or encryption, creating unnecessary exposure. Building security checks directly into the pipeline, rather than bolting them on afterward, protects both the organization and the people whose data is being processed.
The Human Side of Pipeline Work
It's easy to think of this work as purely technical, but the strongest teams treat pipeline development as a collaborative effort between engineers and the people who actually use the data. Regular conversations with analysts and business stakeholders reveal gaps that no amount of code review would catch. A field that seems irrelevant to an engineer might be critical to a finance analyst closing the books each month.
Maintaining reliable data engineering pipelines is less about chasing the newest tool and more about discipline: testing changes before deployment, monitoring systems continuously, and staying honest about technical debt instead of letting it accumulate silently.
Final Thoughts
Data engineering pipelines rarely get the spotlight, but they determine whether an organization's data can be trusted at all. Investing in thoughtful design, consistent validation, and clear communication pays off far beyond the engineering team, shaping the quality of every decision built on that data. As data volumes keep growing, the organizations that treat their pipelines as a core product rather than background plumbing will scale with the most confidence.

 Arabic
 French
 Spanish
 Portuguese
 Deutsch
 Turkish
 Dutch
 Italiano
 Russian
 Romaian
 Portuguese (Brazil)
 Greek