


Building Efficient Hybrid Data Pipeline Solutions
Introduction
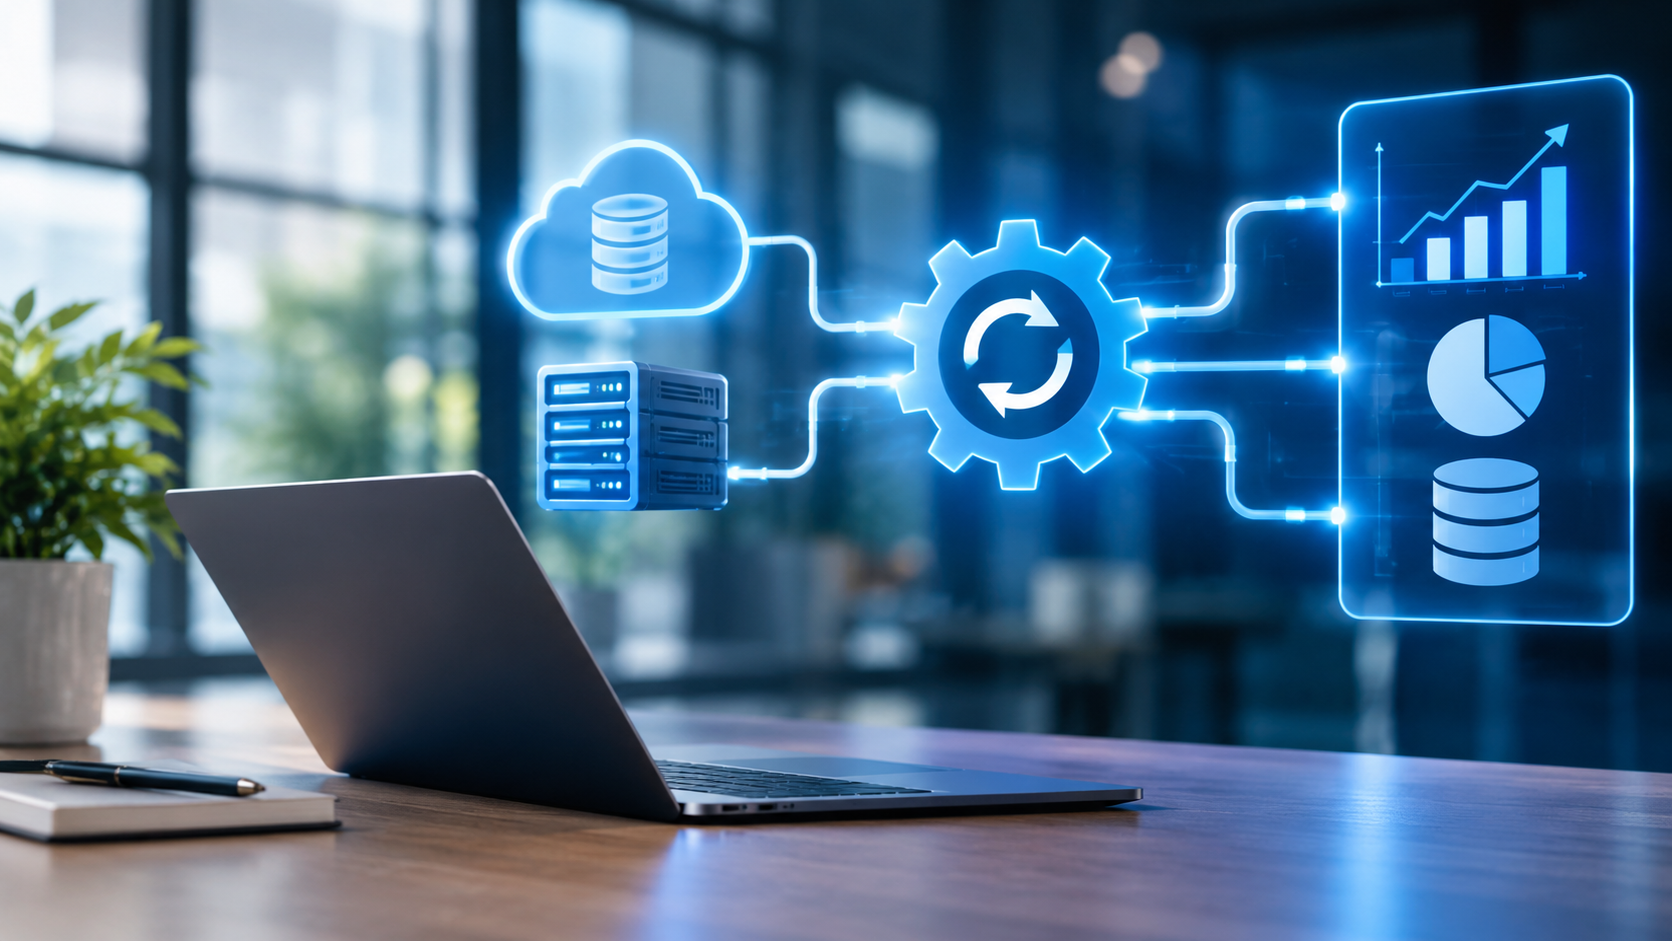
In the modern digital landscape, organizations generate and process massive volumes of information at unprecedented speeds. Managing this influx requires robust technological frameworks that can seamlessly bridge legacy systems and modern cloud environments. Enter the hybrid data pipeline, a powerful architectural approach designed to unify disparate storage systems, on-premises servers, and multi-cloud platforms. Organizations striving to maintain a competitive edge rely heavily on a hybrid data pipeline to ensure continuous data flow, real-time analytics, and secure governance across every operational tier. Without a well-designed hybrid data pipeline, enterprises often struggle with data silos, slow query response times, and fragmented insights that hinder strategic decision-making.
Understanding Architecture Fundamentals
At its core, a hybrid data pipeline acts as the connective tissue linking local data centers with public cloud infrastructure. Traditional data integration methods often fall short when dealing with the dynamic workloads typical of modern enterprises. By deploying a flexible hybrid data pipeline, data engineers can ingest, transform, and load information from edge devices, legacy databases, and cloud data warehouses without friction. This architectural model empowers businesses to process sensitive information locally for compliance purposes while leveraging elastic cloud compute resources for heavy analytical workloads. Implementing a scalable hybrid data pipeline requires careful planning around network latency, data serialization formats, and secure transmission protocols to prevent bottlenecks during peak utilization periods.
Overcoming Integration Challenges
Deploying a reliable hybrid data pipeline introduces specific engineering hurdles that demand careful mitigation. Data velocity, variety, and volume can quickly overwhelm poorly configured integration frameworks. When setting up a hybrid data pipeline, architects frequently encounter issues related to schema drift, network instability, and synchronization lag between on-premises repositories and cloud destinations. Addressing these challenges involves adopting automated schema evolution tools and implementing robust error-handling mechanisms within the hybrid data pipeline itself. Furthermore, monitoring tools must track the health of the hybrid data pipeline continuously, alerting administrators to dropped packets, authentication failures, or unexpected latency spikes before they impact downstream business intelligence dashboards.
Ensuring Security and Compliance
Data privacy regulations mandate stringent controls over how sensitive information moves across network boundaries. A secure hybrid data pipeline incorporates encryption standards both in transit and at rest, ensuring that corporate assets remain protected against unauthorized interception. Designing a compliant hybrid data pipeline involves establishing strict access controls, role-based permissions, and comprehensive audit logs that track every movement of sensitive records. Organizations utilizing a hybrid data pipeline can successfully balance regulatory mandates with operational agility by keeping customer PII within secure on-premises perimeters while routing anonymized operational metrics to cloud environments for machine learning model training and trend analysis.
Optimizing Performance and Cost
Resource allocation directly impacts both the speed and financial sustainability of enterprise data operations. An optimized hybrid data pipeline intelligently routes workloads based on cost efficiency and compute requirements. For instance, routine batch processing jobs can be scheduled during off-peak hours using economical cloud instances, while real-time streaming events flow continuously through the hybrid data pipeline to support immediate customer-facing applications. Fine-tuning the hybrid data pipeline involves compressing payloads, leveraging incremental data loads instead of full table refreshes, and utilizing edge caching mechanisms to minimize redundant cloud egress charges. Through meticulous performance tuning, data teams can maximize the throughput of their hybrid data pipeline while keeping operational expenditures predictable and manageable.
Future Trends and Evolution
The technological landscape surrounding enterprise data management continues to evolve at a rapid pace. Emerging paradigms such as data mesh and automated data governance are reshaping how organizations conceptualize information flow. In this shifting environment, the modern hybrid data pipeline is becoming more intelligent, leveraging artificial intelligence to self-heal schema mismatches and predict pipeline failures before they disrupt operations. As edge computing expands and Internet of Things devices generate decentralized streams of information, the strategic importance of a resilient hybrid data pipeline will only intensify. Organizations that invest in modernizing their hybrid data pipeline infrastructure today will be exceptionally well-positioned to harness future technological breakthroughs, drive meaningful insights, and maintain absolute operational excellence across all hybrid environments.

 Arabic
 French
 Spanish
 Portuguese
 Deutsch
 Turkish
 Dutch
 Italiano
 Russian
 Romaian
 Portuguese (Brazil)
 Greek